The developer community is increasingly prioritizing the optimization of open-source AI models to achieve greater performance and cost-efficiency, a critical trend for wider AI adoption across diverse applications.
Large language models (LLMs) and other advanced AI architectures, while powerful, often demand substantial computational resources for inference. This translates directly into higher operational costs, particularly when deployed at scale on cloud infrastructure providers like Amazon Web Services (AWS), Google Cloud Platform (GCP), or Microsoft Azure. For many developers and organizations, these costs can be a significant barrier to entry or expansion. The inherently flexible nature of open-source models, however, provides a unique opportunity to apply various optimization techniques that can dramatically reduce resource requirements without compromising core capabilities.
The Imperative for Optimization
The drive to optimize stems from several key challenges presented by unoptimized models:
- High Inference Costs: Running large models frequently incurs significant charges for GPU usage, memory, and data transfer on cloud platforms.
- Latency Issues: Complex models can have high inference latency, impacting real-time applications and user experience.
- Deployment Constraints: Many powerful models are too large or computationally intensive for deployment on edge devices, mobile phones, or even smaller data center instances.
- Energy Consumption: The continuous operation of large, unoptimized models contributes to higher energy usage and associated environmental impact.
By addressing these challenges, optimization makes advanced AI more accessible and sustainable.
Key Optimization Strategies
Developers employ a range of techniques to streamline open-source AI models. These methods often focus on reducing model size, computational complexity, or both:
- Quantization: This technique reduces the precision of the numerical representations used in a model. For example, converting floating-point numbers (e.g., FP32 or FP16) to lower-bit integers (e.g., INT8 or INT4) can significantly shrink model size and speed up computation, as lower-precision arithmetic is faster on many modern processors and GPUs. While there can be a slight trade-off in accuracy, careful post-training quantization (PTQ) or quantization-aware training (QAT) can mitigate this.
- Pruning: Pruning involves removing redundant or less important connections (weights) or entire neurons from a neural network. Structured pruning removes entire channels or layers, leading to more regular, hardware-friendly sparse models, while unstructured pruning removes individual weights. This can reduce model size and the number of operations required during inference.
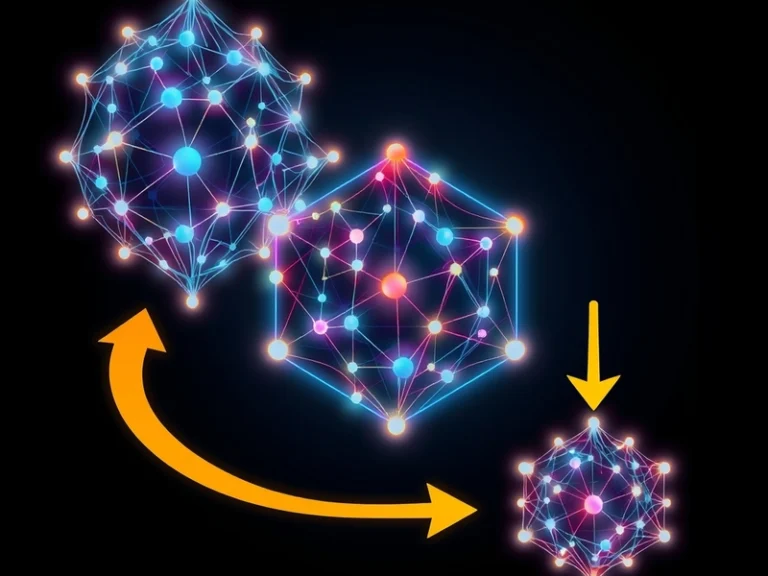
- Knowledge Distillation: In this approach, a smaller, “student” model is trained to mimic the behavior of a larger, more complex “teacher” model. The student model learns to reproduce the outputs or internal representations of the teacher, often achieving comparable performance with significantly fewer parameters and faster inference times.
- Model Architecture Search (NAS) and Efficient Architectures: Instead of optimizing an existing large model, developers can explore or design inherently more efficient architectures. Examples include models specifically designed for mobile or edge devices, such as MobileNet or EfficientNet, which use techniques like depthwise separable convolutions to reduce parameters and computations. The open-source community actively develops and shares optimized variants of popular models, such as various LLaMA derivatives.
- Compiler and Runtime Optimizations: Specialized AI compilers and runtimes can analyze a model graph and optimize its execution for specific hardware. Tools like NVIDIA’s TensorRT, Microsoft’s ONNX Runtime, and Intel’s OpenVINO toolkit are designed to accelerate inference by applying graph optimizations, kernel fusion, and hardware-specific code generation.
- Batching: Processing multiple input requests simultaneously in “batches” can significantly improve GPU utilization and throughput, especially for models with high parallelization potential. This is a common strategy in production environments but can introduce latency if not managed carefully.
The Role of Open Source and Community
The open-source nature of many leading AI models, such as Meta’s LLaMA series, Mistral AI’s Mixtral 8x7B, and Stability AI’s Stable Diffusion, is fundamental to this optimization trend. Their public availability fosters a vibrant community of researchers and developers who contribute to:
- Fine-tuning and Adaptation: Users can fine-tune these models on specific datasets, often leading to smaller, more specialized models that perform well on particular tasks.
- Tooling and Frameworks: Platforms like Hugging Face provide a vast ecosystem of pre-trained models, datasets, and tools (e.g., Transformers, Accelerate, Optimum libraries) that simplify the process of loading, fine-tuning, and optimizing models. Their integration with various quantization and compilation tools democratizes access to these advanced techniques.
- Benchmarking and Sharing: The community actively benchmarks optimized variants and shares findings, allowing others to leverage proven strategies and pre-optimized models.
- Hardware-Specific Implementations: Developers often create and share versions of models optimized for particular hardware platforms, from high-end GPUs to consumer-grade CPUs and edge AI accelerators.
Tangible Benefits for Developers
By embracing these optimization techniques, developers can unlock substantial benefits:
- Reduced Operational Costs: Lower compute requirements directly translate to reduced cloud bills, making AI deployment more economically viable for startups and individual developers.
- Improved Performance: Faster inference times lead to more responsive applications and better user experiences.
- Expanded Deployment Options: Optimized models can run on less powerful hardware, enabling deployment on edge devices, embedded systems, or within resource-constrained environments.
- Enhanced Accessibility: Lower barriers to entry mean more developers can experiment with and deploy advanced AI, fostering innovation.
- Sustainability: More efficient models consume less energy, contributing to greener AI practices.
The ongoing push to optimize open-source AI models is not merely about incremental improvements; it represents a fundamental shift towards making powerful AI more practical, affordable, and pervasive across the technological landscape. As models continue to grow in complexity, the ability to efficiently distill their power into lean, high-performing deployments will remain a cornerstone of AI development.