The concept of self-improving artificial intelligence, long a subject of theoretical discussion, is increasingly being framed within actionable research roadmaps, with recent discussions outlining potential multi-step frameworks for recursive AI enhancement. These frameworks aim to guide the development of systems capable of autonomously identifying their limitations, generating or acquiring new knowledge, and subsequently refining their own algorithms or architectures to improve performance.
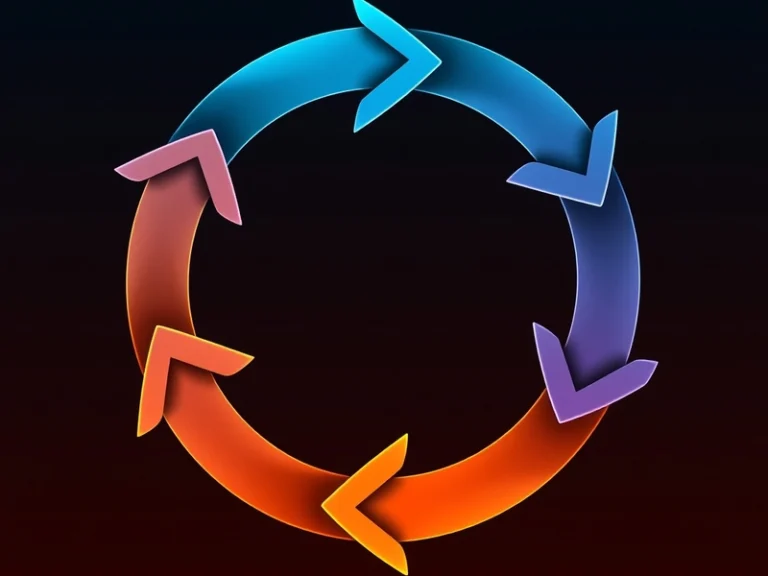
The pursuit of truly self-improving AI represents a significant frontier in the field, moving beyond models that learn from static datasets to those that can continuously evolve and adapt. While full autonomous self-modification remains a distant goal, the principles of recursive self-improvement are already being explored through techniques that enable AI systems to refine specific aspects of their operation or learning process. This typically involves a cyclical process where an AI system generates new insights or data, uses that information to update its internal parameters or structure, and then evaluates the impact of those changes, initiating a new cycle of improvement.
A Five-Step Map Toward Recursive AI Enhancement
Developing AI systems that can genuinely enhance their own capabilities requires a structured approach. While specific implementations vary widely depending on the AI’s domain and architecture, a generalized five-step map can outline the core processes involved in recursive self-improvement:
Step 1: Baseline Establishment and Goal Definition
The initial phase involves creating an AI system with a foundational set of capabilities and defining clear, measurable performance metrics. This baseline model is trained on an initial dataset for a specific task, establishing its starting performance level. Crucially, this step also involves defining the overarching goals for self-improvement—what aspects of performance are targeted for enhancement (e.g., accuracy, efficiency, robustness, generalization)? Without clear objectives, the direction of improvement can become unfocused.
- Initial Model Training: Developing a functional AI model (e.g., a deep neural network, a reinforcement learning agent) using existing datasets and standard training methodologies.
- Metric Definition: Establishing quantitative measures for success and failure relevant to the AI’s task, such as F1-score for classification, reward accumulation for agents, or inference latency.
- Scope Identification: Pinpointing specific areas where the AI is expected to improve, which could range from handling novel data distributions to optimizing computational resources.
Step 2: Performance Monitoring and Error Identification
Once deployed or in operation, the AI system’s performance must be continuously monitored against the defined metrics. This step focuses on identifying instances where the AI performs suboptimally, makes errors, or encounters situations it cannot effectively handle. Effective error identification is critical for directing the self-improvement process toward genuine weaknesses rather than perceived ones.
Techniques employed here can include:
- Continuous Evaluation: Regularly testing the AI against new, unseen data or in real-world scenarios.
- Anomaly Detection: Identifying outputs or behaviors that deviate significantly from expected norms.
- Root Cause Analysis: Attempting to understand why an error occurred, whether due to insufficient training data, model bias, architectural limitations, or environmental shifts. This can involve explainable AI (XAI) techniques to gain insight into the model’s decision-making process.
- Adversarial Analysis: Probing the model with intentionally challenging or adversarial inputs to uncover vulnerabilities and robustness issues.
Step 3: Learning Resource Generation and Acquisition
Upon identifying areas for improvement, the AI system (or its supervisory framework) needs to acquire or generate new learning resources to address these deficiencies. This is a pivotal step, as it directly feeds the recursive learning process. This can manifest in several ways:
- Active Learning: The AI intelligently queries human annotators for labels on specific, high-uncertainty data points that would be most beneficial for its learning.
- Synthetic Data Generation: Creating new, relevant training examples programmatically, often using generative models like Generative Adversarial Networks (GANs) or diffusion models, to cover identified gaps or edge cases.
- Self-Play: In reinforcement learning, agents can play against themselves (as seen with AlphaGo or AlphaZero) to generate vast amounts of unique training data and discover novel strategies.
- Knowledge Augmentation: Automatically searching and integrating external information sources (e.g., databases, web content) to expand its knowledge base.
- Feedback Loops: Incorporating direct human feedback, user interactions, or environmental observations as new training signals.
Step 4: Model Refinement and Adaptation
With new learning resources in hand, the AI system undergoes a process of refinement and adaptation. This step involves updating the model’s internal state, parameters, or even its architecture to integrate the new knowledge and address identified weaknesses. This is where the “improvement” tangibly occurs.
Common techniques include:
- Retraining and Fine-tuning: Re-training the model on the expanded or augmented dataset, potentially with adjusted learning rates or optimization schedules.
- Parameter Optimization: Automatically adjusting hyperparameters (e.g., learning rate, regularization strength) to achieve better performance on the new data.
- Neural Architecture Search (NAS): In more advanced scenarios, the AI might explore and propose modifications to its own neural network architecture to better suit the evolving task or data.
- Transfer Learning and Meta-Learning: Leveraging knowledge from related tasks or learning “how to learn” more effectively from new data distributions.
- Algorithm Modification: In highly advanced systems, the AI might even suggest or implement changes to its own learning algorithms, though this is largely theoretical in current practical applications.
Step 5: Iterative Deployment and Feedback Loop
The final step involves deploying the refined AI system back into its operational environment and restarting the cycle. The improved model’s performance is again monitored, and any new errors or areas for further enhancement are identified, leading back to Step 2. This recursive loop is fundamental to continuous self-improvement, allowing the AI to progressively enhance its capabilities over time.
Effective implementation of this step requires robust version control, A/B testing capabilities, and mechanisms to safely roll out updates while monitoring for unintended side effects or regressions. The goal is a persistent feedback loop that drives incremental, yet cumulative, advancements in the AI’s intelligence and utility.
While a fully autonomous, general-purpose self-improving AI remains a long-term aspiration, these five steps provide a conceptual framework for current research and development efforts. By breaking down the complex challenge of recursive self-improvement into manageable, interconnected processes, researchers are actively building systems that can learn not just from data, but from their own experiences and limitations, paving the way for more robust and capable AI.